OpenAI's ChatGPT Relies on Patchwork of Crawlers and Third-Party APIs, Including SerpApi — Which Google Is Suing
A new analysis by Olivier de Segonzac maps the layered data pipeline behind ChatGPT's real-time web answers, revealing OpenAI's proprietary Labrador bots, Bing's image index, and SerpApi — the latter currently the target of a Google lawsuit over unauthorized scraping. A federal judge in September 2026 rejected SerpApi's bid to compel Google to disclose licensing agreements.
A new analysis has exposed the layered supply chain of crawlers and third-party application programming interfaces (APIs) that feeds real-time answers in ChatGPT — a system more complex than most users assume, and one that includes a data provider currently being sued by Google.
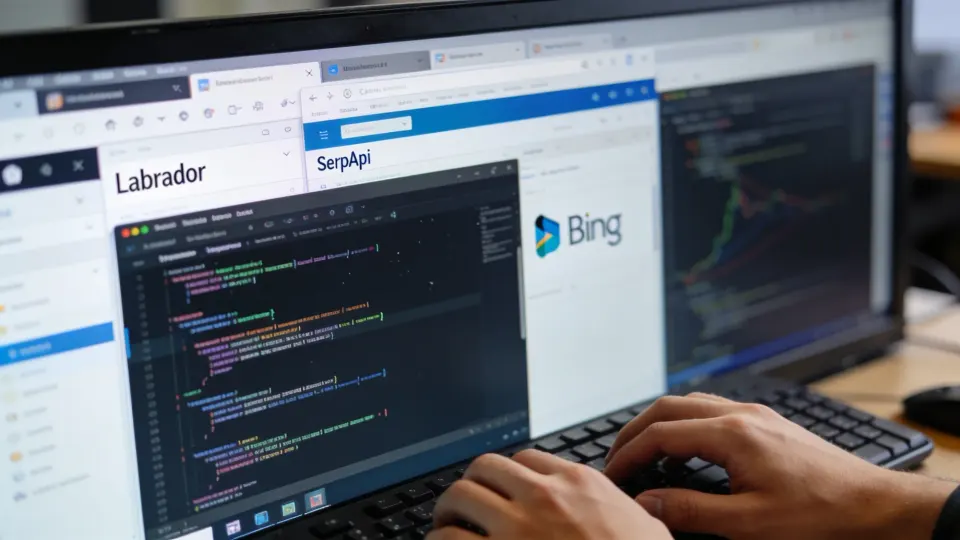
Olivier de Segonzac investigated the data flows behind ChatGPT's search capabilities and found that OpenAI relies on a mix of in-house bots and external services. At the centre of the proprietary side is a crawler called Labrador, which comes in several specialised versions: labrador-news-all, labrador-news-7d, labrador-wiki, labrador-web-fallback, labrador-images-nocache, and labrador-arxiv, covering news, Wikipedia, fallback web pages, images, and academic sources respectively.
For image results, ChatGPT draws on Bing's index. For Google web results, it relies on SerpApi — even as Google and SerpApi are engaged in active litigation. According to the analysis, free ChatGPT users typically receive answers sourced from Labrador's own crawl, while more complex or premium queries may trigger Bing or SerpApi.
Google's Lawsuit Against SerpApi
Google filed its lawsuit against SerpApi in 2025, with the case updated in 2026. The core allegation, as detailed in a Bloomberg Law case report, is that SerpApi scraped and resold Google's search results without permission, breaking anti-circumvention rules and intellectual property laws.
In September 2026, a federal judge rejected SerpApi's attempt to compel Google to disclose its licensing agreements, ruling that standard pretrial discovery procedures must be followed. Separately, by August 2026, Google had confirmed the rollout of google.com/goto redirect links, a technical measure described as part of its broader effort against automated data extraction.
Implications for Publishers and Content Visibility
The analysis notes that OpenAI's continued use of SerpApi — despite the pending litigation — signals a willingness to navigate legal uncertainty in order to broaden its data sourcing. At the same time, the heavy deployment of Labrador indicates OpenAI is building its own index while remaining dependent on outside feeds.
For publishers and SEO professionals, the findings suggest that visibility in ChatGPT's answers is determined not solely by rankings on Google or Bing, but also by how Labrador crawls and indexes content. The shifting legal and technical landscape around AI data pipelines is increasingly relevant to decisions about content distribution and discoverability.
Prepared with AI assistance and reviewed by the editorial team.